Skip to content

BALASAGUN · BRAINSTORM's own language model

Balasagun: the city of the Kutadgu Bilig

Balasagun was one of the capitals of the Karakhanids, in the basin of the Chu River in today's Kyrgyzstan. Yusuf Has Hacib, author of the Kutadgu Bilig, was born in this city and began his work here; he completed it in Kashgar in 1069–70.

Kutadgu Bilig means “the knowledge of being happy”. Our model takes its name from this city.

Create your own language model.

An AI language model made for you, living and working on your own server or on rented GPUs. It speaks the language of your business; unless you choose otherwise, your questions and documents never go to another AI company.

Status

In development · Stage 0 / 3 · October 2026

How it works

The model lives on your server

YOUR SERVER · or rented GPU011011001001101101EXTERNAL AI SERVICE✕YOUR SYSTEMSPMS · ERP · SCADAYOUR DOCUMENTSregulations · policiesBALASAGUNon your serverBALASAGUNTOOLScalculations · work ordersUSERSRoom 304: the air conditioningisn't working.room 304 · maintenance logopen work order: AC, room 304A work order is open;the team is on its way.The flat's installed load is 12 kW.What is the demand load?Electrical Installations Reg.Art. 57 · diversity factors8 kW × 0.6 + 4 kW × 0.4Demand load: 6.4 kW.Source: Installations Reg. Art. 57

Animation: how it is meant to work. The model is still in development.

HOTEL

  1. A guest writes to reception: “The air conditioning in room 304 isn't working.”
  2. BALASAGUN runs on the hotel's own server; the question goes to no other company.
  3. It checks the room's maintenance log and the hotel system.
  4. It opens a work order for technical service.
  5. The answer goes back to the guest; the work order is with technical service.

ELECTRICAL

  1. An engineer asks: “The flat's installed load is 12 kW. What is the demand load?”
  2. The model thinks on your server.
  3. It reads the diversity rule from the regulation itself, not from memory.
  4. It calculates with a tool: 0.6 for the first 8 kW, 0.4 for the rest.
  5. The answer returns with its source: a demand load of 6.4 kW.
  1. 1 · A question arrivesa guest, staff member or engineer asks
  2. 2 · The model thinkson your server, without going to another company
  3. 3 · It checks the sourceregulation, maintenance log, hotel policy
  4. 4 · It actscalculates, opens a work order
  5. 5 · The answer returnstogether with its source

What is BALASAGUN?

Our own language model for electrical engineering and hotels

BALASAGUN is the AI language model we are training right now for electrical engineering and hotel management. We don't train from scratch: we take open-source language models, train them with our own engineering know-how for the sector in question, and put them into service and run them. So instead of paying for expensive language models, we build solutions with our own language model. We can also configure the LLM we develop for you to work in a hybrid setup with any other LLMs you choose.

  • Hotel management

    Guest questions, technical service, energy and maintenance tracking, staff tasks. The hotel's own rules and prices are read from its documents with every question.

  • Electrical engineering

    Turkish regulations on electrical installations, earthing and heavy-current (power) installations; voltage drop, demand load, survey and quantity take-off calculations.

  • First users: our own products

    The Elektrik GPT survey software, Leyla, the assistant on this site, and ARI Energy Monitoring will be the first products to use BALASAGUN.

    Elektrik GPTEnergy Platform

How we do it

Your model in five steps

Every model goes through the same five steps. This is how we are training BALASAGUN, and how we build yours.

How it grows

From an open model to your model

YOUR DEDICATED SETUP✓✓✓OUR TEST SETbase modeladapted modeltarget: base + 10 pts or moreOPEN MODELApache 2.0YOUR KNOWLEDGEexpert-approvedGPU · FINE-TUNINGLoRAYOUR OWN SERVERRENTED GPUdedicated to you
  1. A base model licensed for commercial use (Apache 2.0) is chosen. No training from scratch.
  2. Regulations, your own documents and expert-approved rules are added; every record's source is tracked.
  3. Fine-tuning with LoRA on a GPU: the model learns the language of your business.
  4. It is tested on our own test set. If it can't beat the base model, it doesn't go live.
  5. It is installed on your own server or on a rented GPU dedicated to you.
  1. 1 · An open model is chosenApache 2.0, licensed for commercial use; the licence is read from the model card
  2. 2 · Your knowledge is addedregulations, your documents, expert-approved rules; every record's source is tracked
  3. 3 · Fine-tuning on a GPULoRA; no training from scratch
  4. 4 · The examour own test set; if it can't beat the base model, it doesn't go live
  5. 5 · Installed for youyour own server or a rented GPU dedicated to you; for personal data we recommend your own server

Our promises

Four promises

  • Your data under your control

    The model is trained and runs on your own server or on a rented GPU dedicated to you. For models that will process personal data, we recommend your own server. Sending requests to another AI company's cloud model happens only for tasks you choose, and only if you want it.

  • A clearly licensed model, traceable data

    The base model is always licensed for commercial use (Apache 2.0 / MIT). Every training record keeps its source and licence note, and can be removed from training with a single command.

  • No memorising

    Information that changes, such as prices, article numbers and policies, is never memorised by the model; it is read from the document for every question. When the information changes, the model doesn't need retraining.

  • Nothing goes live unmeasured

    Every version is compared with the base model on our own test set; a version that doesn't beat it is not used. Our target for BALASAGUN's first version: at least 10 points better overall, and no area more than 2 points worse.

Where we are now

Honest status

The first version has not been trained yet; we update this section as we go.

  1. 0now

    Test set and base model race

  2. 1

    Data pipeline

  3. 2

    Training the first version (v0.1)

  4. 3

    Serving and integration

  5. v1

    Broader version

Training infrastructure

The BALASAGUN training model

What we have done so far, with the real records: the base model race and the first LoRA trial training. The full training is the next step; here we show exactly what happened.

Base model race

Five open-source models competed on 50 questions from our own test set (25 electrical, 25 hotel); an open-weight judge model scored the answers. The chosen base is Qwen3.6-35B-A3B: first in electrical engineering, licensed Apache-2.0, and suited to serving both domain adapters together on one GPU.

ModelTotalElectricalHotel
google/gemma-4-26B-A4B-it87.276.098.4
Qwen/Qwen3.6-35B-A3Bchosen84.686.482.8
google/gemma-4-12B-it79.664.095.2
Qwen/Qwen3.5-9B73.872.475.2
mistralai/Mistral-Small-3.2-24B-Instruct-250664.655.274.0

Scores out of 100 · judge: Qwen3.8-27B · 19 October 2026
First LoRA trial training

Before the full training we tested the setup end to end: two LoRA adapters (electrical, hotel) were trained for 20 steps each on the same base. Training worked; the following step, serving with vLLM, crashed in this trial and is being fixed.

GPU
NVIDIA A100 SXM 80 GB (rented, RunPod)
VRAM used
69.3 GB (peak 69.6 GB)
Model load
228 s
Training
2 adapters × 20 steps, 42 s
Trained parameters
3,440,640 per adapter (LoRA r=16)
Loss
electrical 3.89 → 0.88 · hotel 2.13 → 0.31
Pod time
17 min; deleted when the job ended
From the pod log (as is)
15:18:59Z {"olay": "yuklendi", "sn": 228.0, "vram_gb": 69.3, "sinif": "Qwen3_5MoeForCausalLM"}
15:19:00Z {"olay": "adaptor", "adaptor": "elektrik", "egitilebilir": 3440640}
15:19:03Z {"olay": "adim", "adaptor": "elektrik", "adim": 0, "loss": 3.892}
15:19:22Z {"olay": "adim", "adaptor": "elektrik", "adim": 19, "loss": 0.8816}
15:19:22Z {"olay": "adaptor", "adaptor": "otel", "egitilebilir": 3440640}
15:19:23Z {"olay": "adim", "adaptor": "otel", "adim": 0, "loss": 2.1289}
15:19:41Z {"olay": "adim", "adaptor": "otel", "adim": 19, "loss": 0.306}
15:19:42Z {"olay": "egitim_bitti", "sn": 270.4, "vram_gb_max": 69.6}
15:20:00Z vLLM version 0.31.0 · model Qwen/Qwen3.6-35B-A3B · lora_modules: elektrik, otel
Durum: BAŞARISIZ — vLLM kapandı (vllm-exited) · GPU: NVIDIA A100-SXM4-80GB · süre: 17 dk

Times in UTC. The lines are our training script's own log.

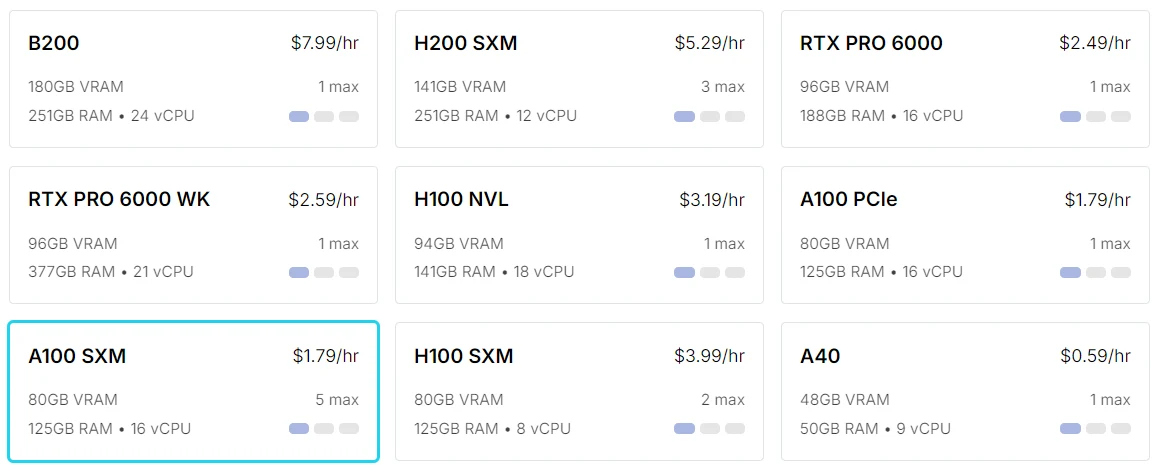
From the RunPod console

GPU cards in the RunPod console; the A100 SXM 80 GB VRAM card is highlighted.
GPU selection: the trial training ran on an A100 SXM 80 GB (highlighted). Prices and stock are live values.
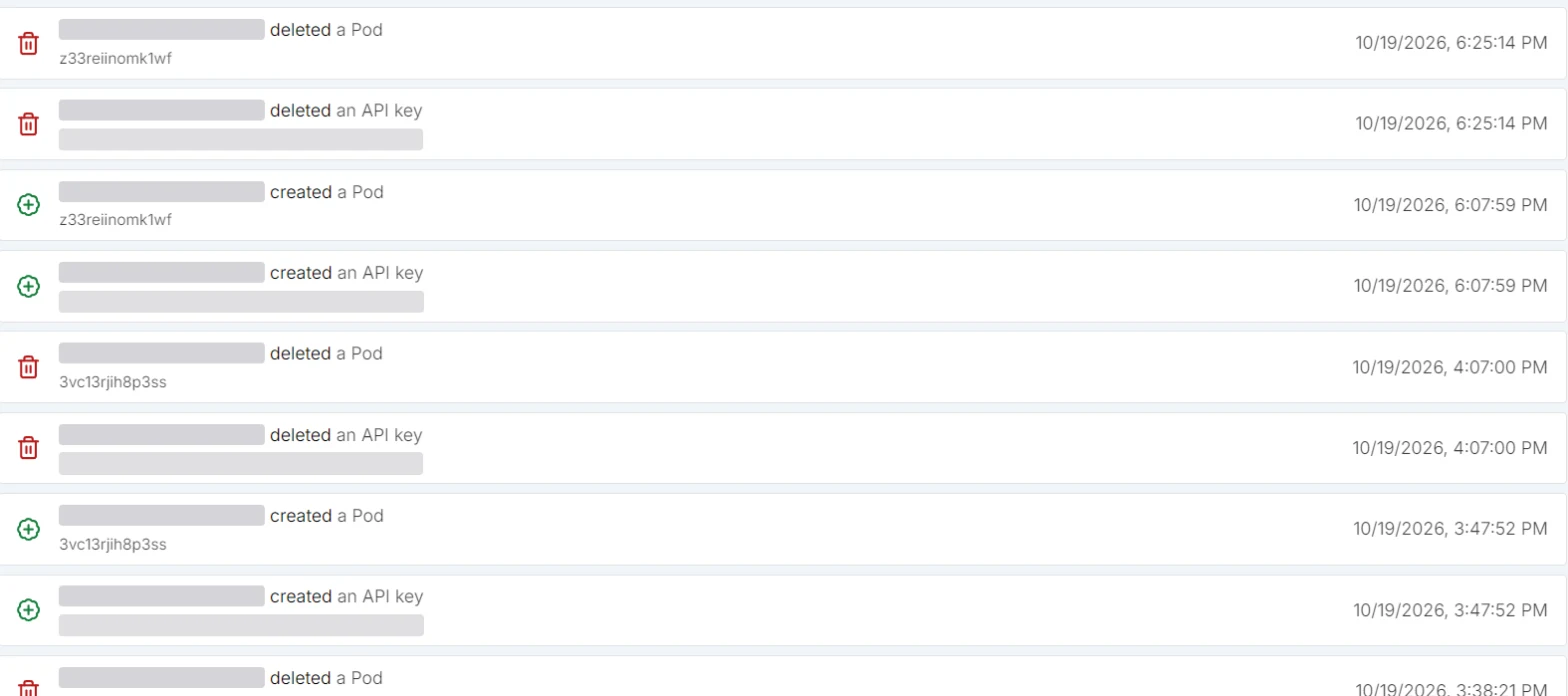
RunPod audit log with pod create and delete rows; e-mail and key IDs are covered.
Audit log: the trial pod was created at 18:07 and deleted at 18:25 (Türkiye time). Account details are covered.

Software we use

  • Qwen3.6-35B-A3B

    base model (Apache-2.0)

  • PyTorch + Hugging Face Transformers

    loading and training the model

  • PEFT (LoRA)

    domain adapters (electrical, hotel)

  • vLLM 0.31.0

    evaluation and serving (OpenAI-compatible endpoint)

  • RunPod GPU pods

    rented A100 80 GB and RTX A6000 48 GB servers

  • Hugging Face Hub

    private repositories for models and adapters

  • Python 3.12 + uv

    data pipeline, test set and scorers

  • Cost guard + Oracle cleaner

    a pod shuts down when its job ends; a forgotten pod is deleted after 1.5 hours

Next: the full training

bf16 LoRA training on expert-approved data, on an 80–96 GB GPU (A100 80 GB or RTX PRO 6000 96 GB). Each adapter is measured on its own domain's test set; a version that does not beat the base model does not go live.

For your sector

We can build one for your sector too.

The way we built BALASAGUN for ourselves, we set up and train your own language model for your sector: on your own server or on rented GPUs.

  • Healthcare

    Patient information, searching protocols and drug guides. Patient data stays on the hospital's server.

  • Law

    Case archive and case-law search, draft petitions. Client files stay in the firm.

  • Finance and accounting

    Invoice reading, regulation questions, account summaries. Financial records stay on the company's server.

  • Manufacturing

    Machine manuals, maintenance logs, fault diagnosis. Production data stays in the factory.

  • Energy and infrastructure

    Field reports, fault logs, plant documents. Grid and plant data stays with you.

  • Public sector and municipalities

    Answers to citizen requests, regulation search. Personal data stays on the institution's server.

  • Education

    Course content and an internal knowledge assistant. Student data stays at the school.

  • Retail and e-commerce

    Product catalogue, customer service, return rules. Customer data stays with you.

Sector not listed? Write to us; let's talk about your business and your data first.Get a quote

Working together

From the first conversation to a working model

Time and price depend on your business and your data; after the discovery meeting we send a written quote.

  1. 1. Discovery meeting

    We talk about your business, your data and your privacy requirements.

  2. 2. Data inventory and test set

    We list which documents and records will be used and build a test set from your real questions.

  3. 3. Pilot model

    We race candidate base models, adapt the winner by fine-tuning and give you the measurement report.

  4. 4. Installation

    We install the model on your own server or on a rented GPU dedicated to you and connect it to your systems.

  5. 5. Maintenance and new versions

    We update the model with new documents and questions and measure every version again.

Server and data centre build-out (F09)

Get a quote

Tell us about your sector and your data; we'll prepare a quote for your own model.

Write briefly about your business and the data you have; we'll get back to you to arrange a discovery meeting.

Pick the line you are interested in

The current situation and the outcome you want is enough.

Your message goes straight to our team. To route it to the right line, the message text is pre-sorted by AI; your name and contact details are not sent to that step.